Infrastructure
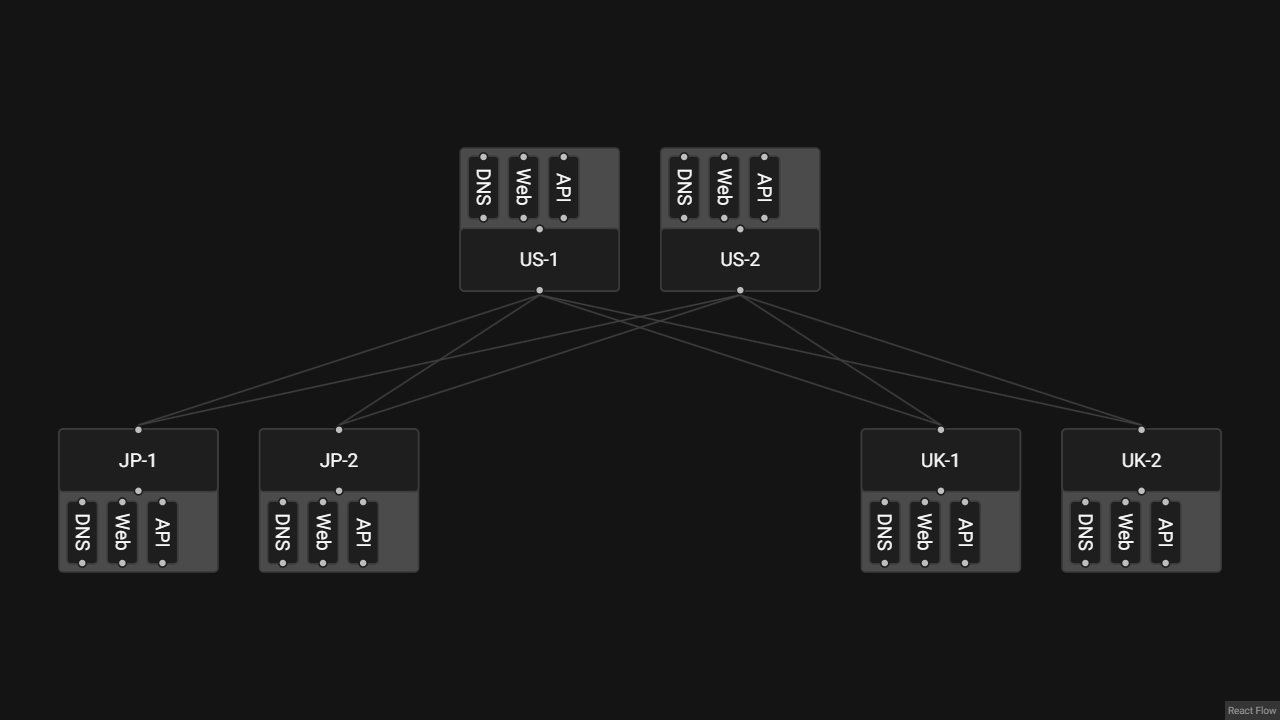
This is the independent infrastructure behind JH0project: websites, DNS, databases, storage, and monitoring. The current fleet uses Docker/Coolify. My Kubernetes/FluxCD experience belongs to ALEASAT, a separate student design-team project.
The six-node fleet spans Japan, the US, and the UK. Limited resources and cross-region latency shape the design. Availability and recovery depend on each service's replication and routing behavior; geographic distribution alone is not a guarantee of fault tolerance.
Architecture
Containerized services share repeatable deployment patterns across the fleet. Stateless application replicas can scale separately from stateful systems such as databases and object storage. Replication, durability, and recovery still need to be considered for each stateful service.
The distributed monitoring case study explains local Prometheus collection and the centralized Thanos query plane. The image CDN case study covers image processing and shared caching.
Software Stack
Databases
CockroachDB is the fleet's distributed SQL database. PostgreSQL-compatible interfaces, multi-region replication, and Prisma integration informed the choice. These are project-specific tradeoffs rather than permanent exclusions of PostgreSQL, YugabyteDB, or Cassandra.
An earlier version used KeyDB to share Next.js caches across servers, including expensive image transformations. Each node had a local cache replica, with asynchronous replication between nodes.
The image-processing path later moved to Imgproxy and Garage. The image CDN case study describes that change and its tradeoffs. The older KeyDB approach is historical context, not a description of the current image service.
DNS
We host our own BIND 9 DNS server mainly for the DN42 network. To allow easy management and versioning of BIND 9 config and the DNS records, we containerized the BIND 9 server and run it as a Docker container on each server. The DNS records are DNSSEC signed, and the DNS server is configured to use DNS over TLS (DoT) for secure DNS queries. To allow it to be highly available, we use anycast to announce the DNS server IP address, and use BGP to select an available route according to routing policy. Health-based announcements support failover when a DNS instance becomes unavailable. ECMP can distribute flows when equal-cost paths are available; it does not guarantee geographically nearest routing or perfectly even distribution.
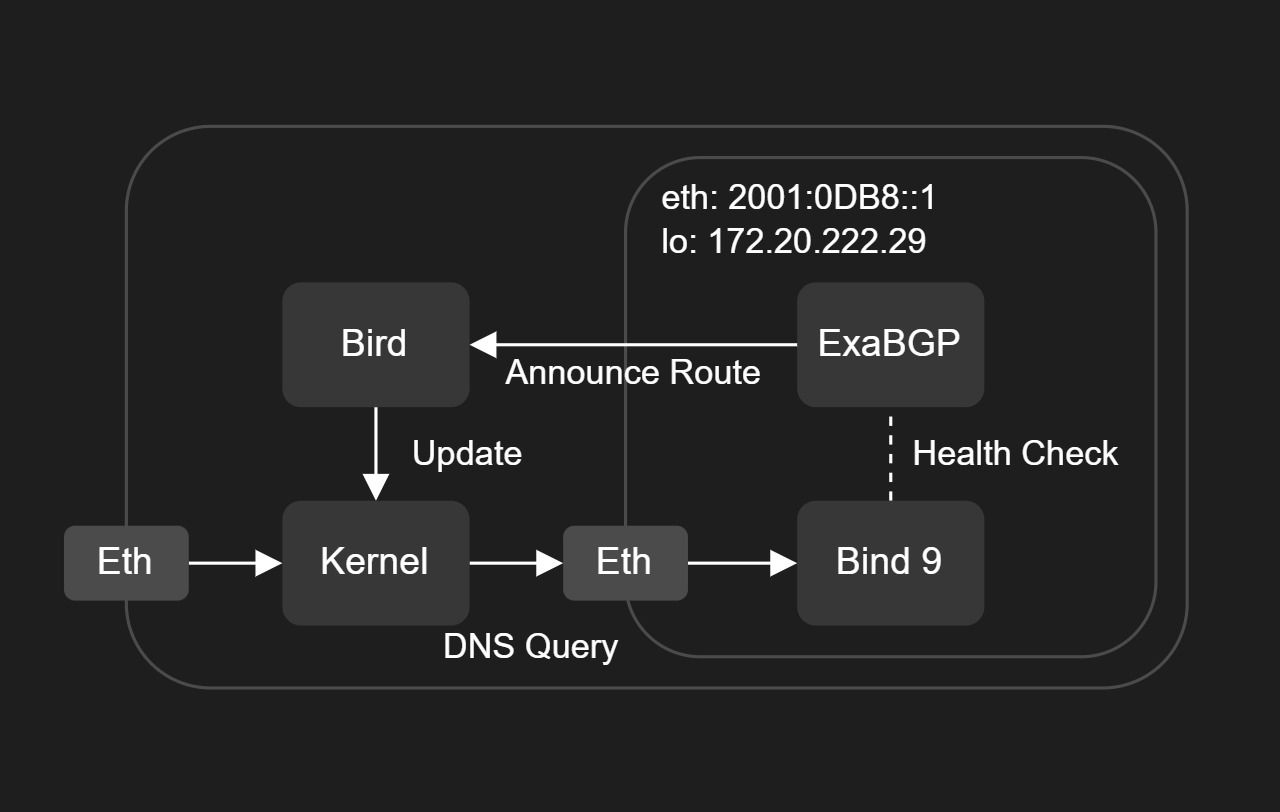 In the container, ExaBGP will monitor the health of the DNS server, and announce the anycast address to Bird, which will then announce the anycast address to the BGP peers. Where equal-cost paths are available and supported by the peers, ECMP can spread flows across those paths.
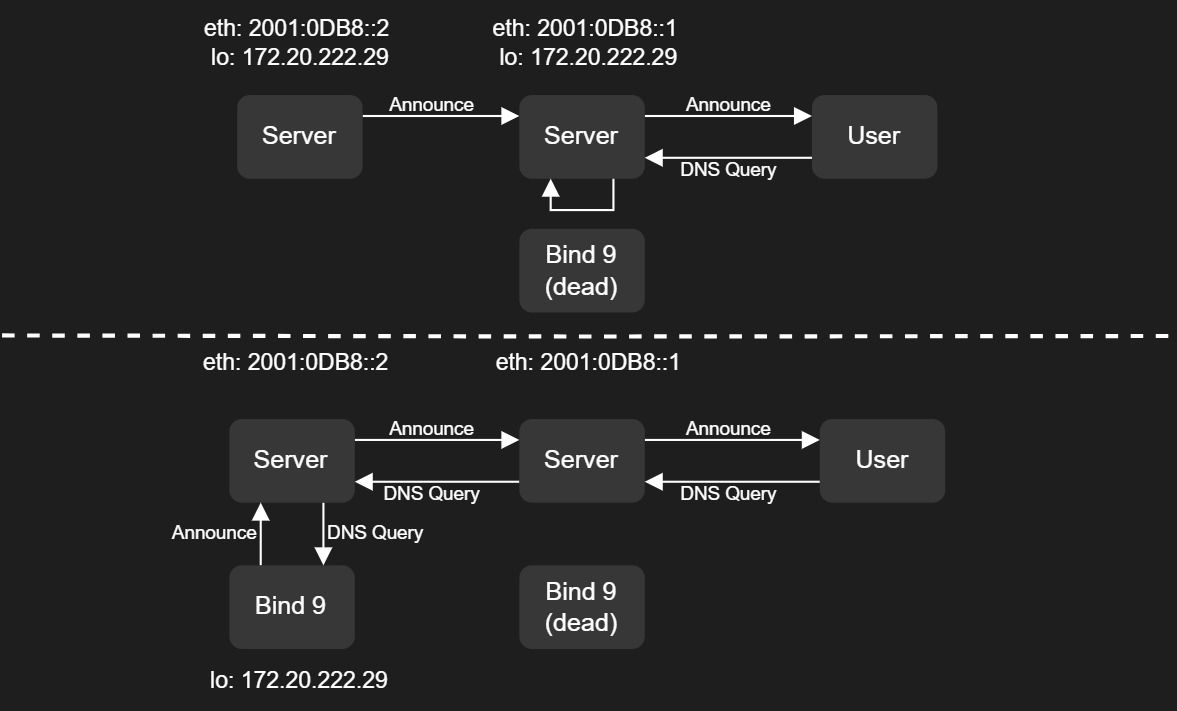 Why do we announce it in the container? Because we can't set the server loopback IP address as the anycast address. If the BIND 9 server goes down, while it will route the traffic to the next nearest server, all DNS queries going through the server will be accepted-ish by the server, but no response will be sent back.
Infrastructure Management
The current fleet runs Docker, managed through Coolify. I chose this approach to limit operational overhead on small servers spread across regions.
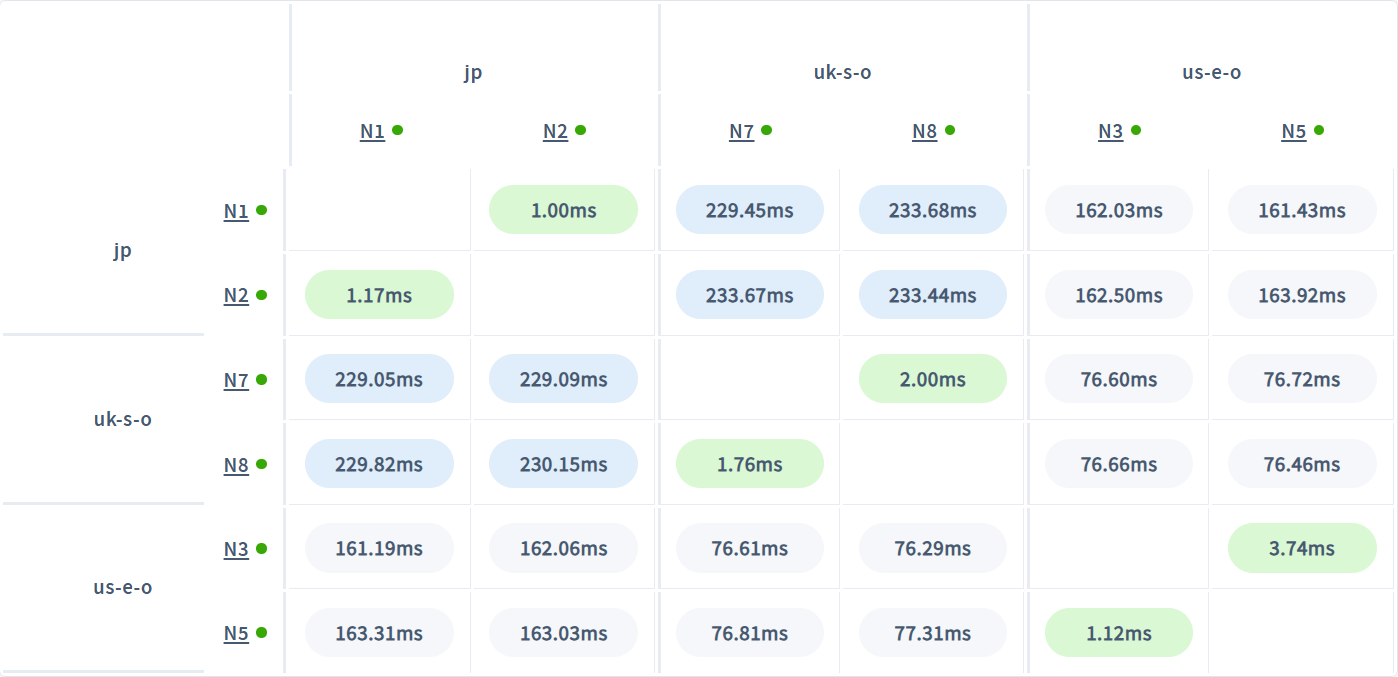 Cross-region latency as shown in the CockroachDB console when this architecture was evaluated.
Latency between regions was observed at up to approximately 266 ms. A wide-area consensus control plane adds latency and recovery tradeoffs. This does not make Kubernetes or etcd impossible: etcd supports heartbeat and election-timeout tuning for higher-latency environments.
With two servers per region, the fleet did not match the control-plane redundancy I wanted for separate regional clusters. Kubernetes can run with a single control plane; a high-availability topology has different redundancy requirements. For this project's workload, Docker/Coolify was the more manageable choice.
This describes the independent JH0project fleet. Kubernetes and FluxCD were used in my ALEASAT work, not this current deployment.